HTML supplies the page structure, CSS its appearance, and JavaScript its interactions. Python handles import preparation and the live server requests. SQLite performs searches using FTS5, its native full-text indexing engine. Node.js is used for local preview and packaging, not the production API. The finite data import and thumbnail preparation jobs have finished; no always-running collection worker is needed.
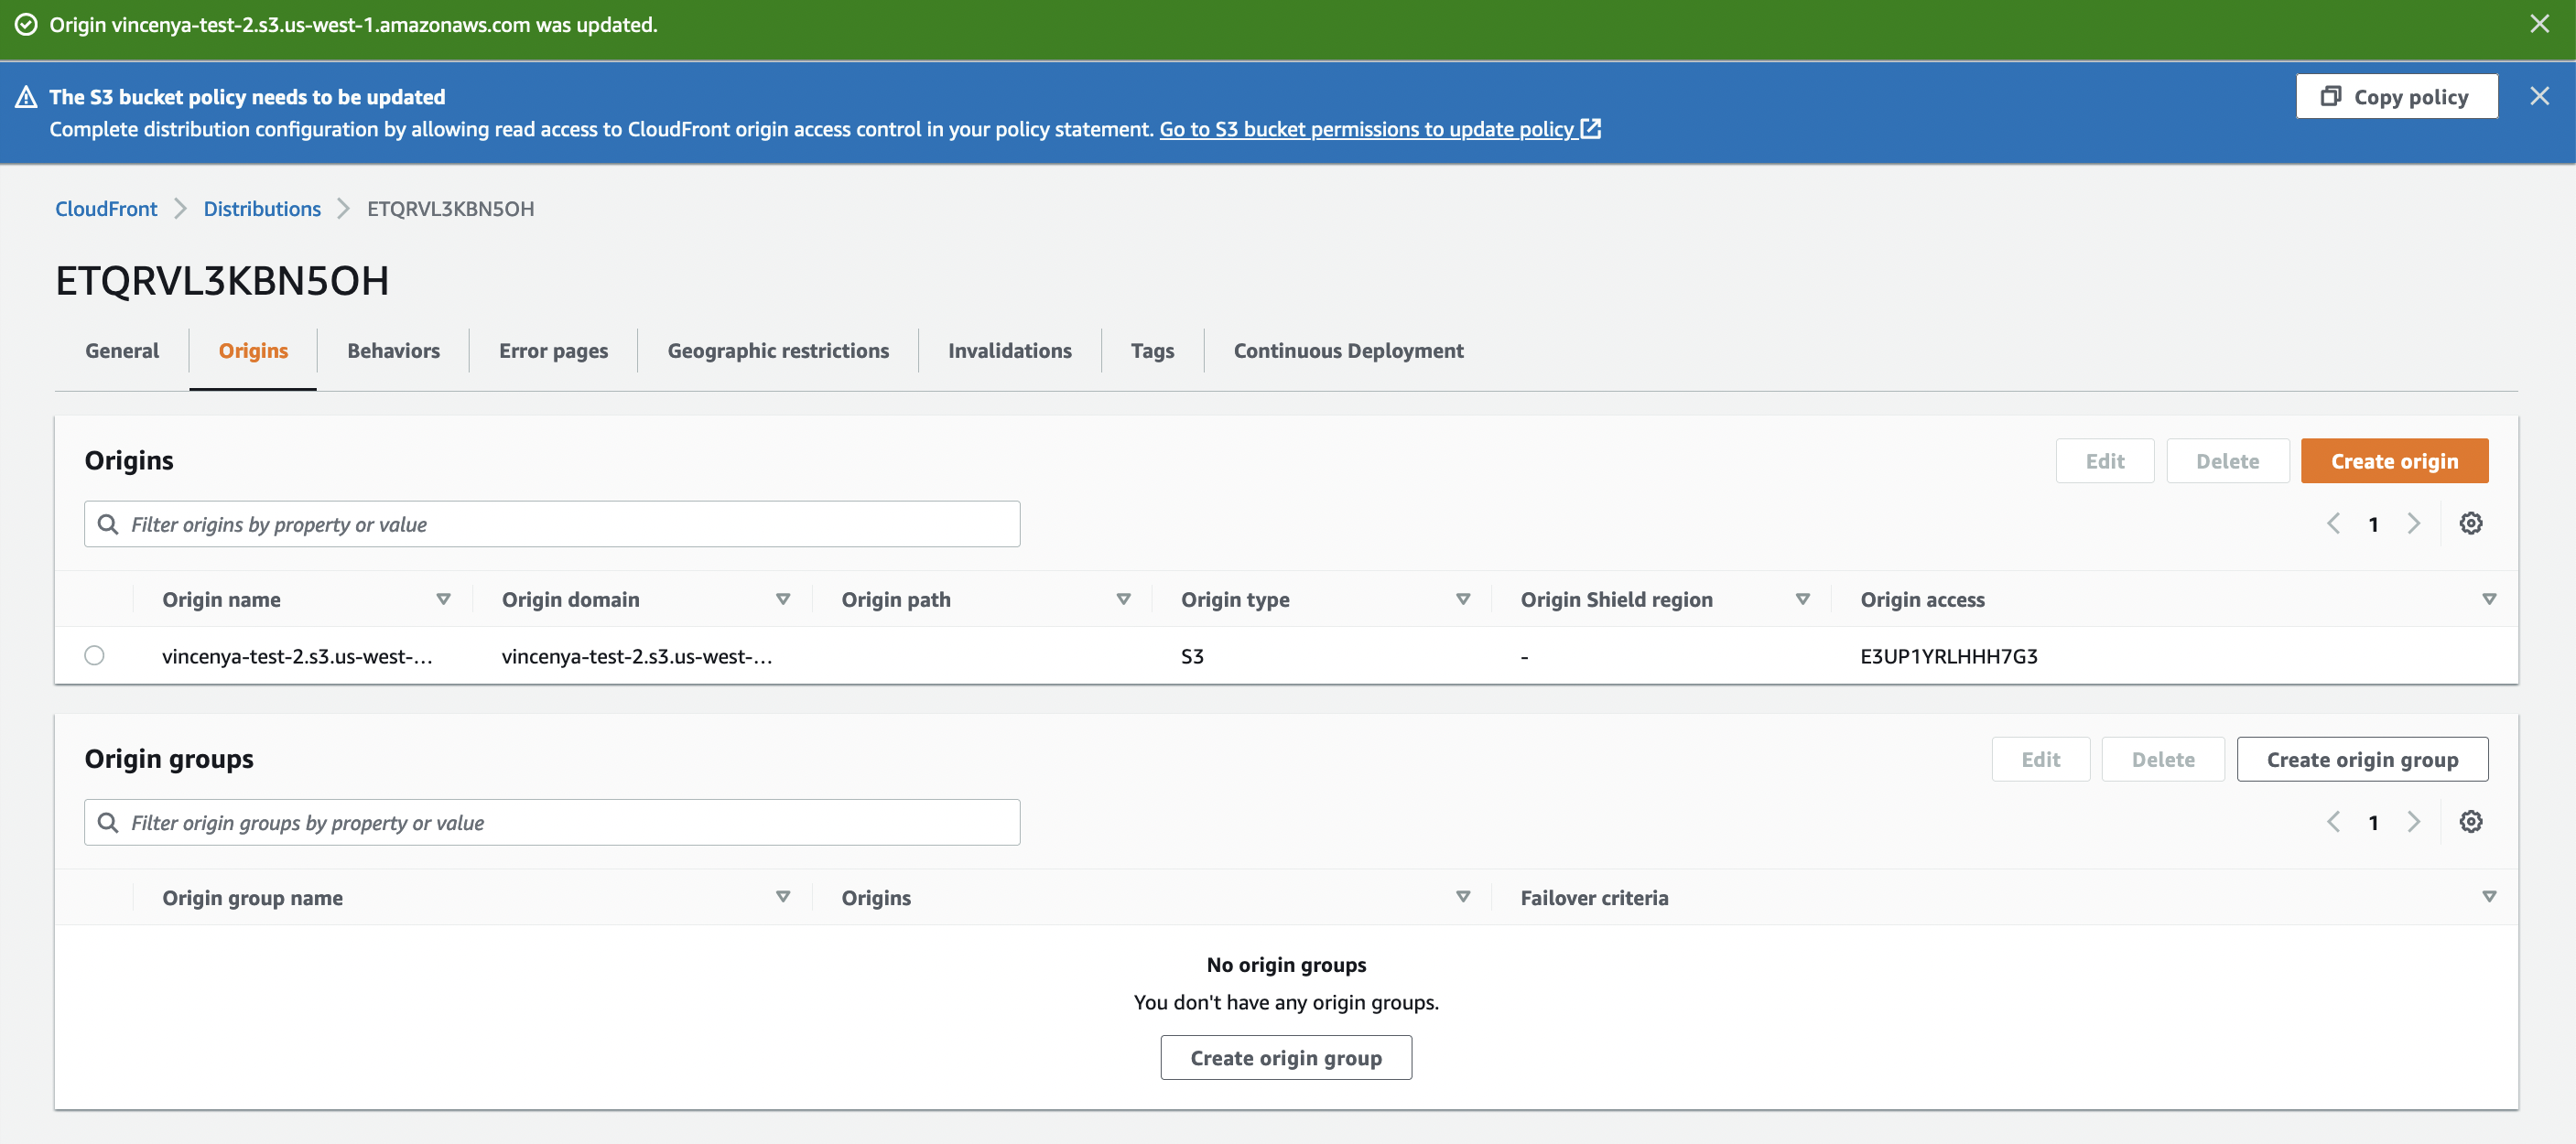
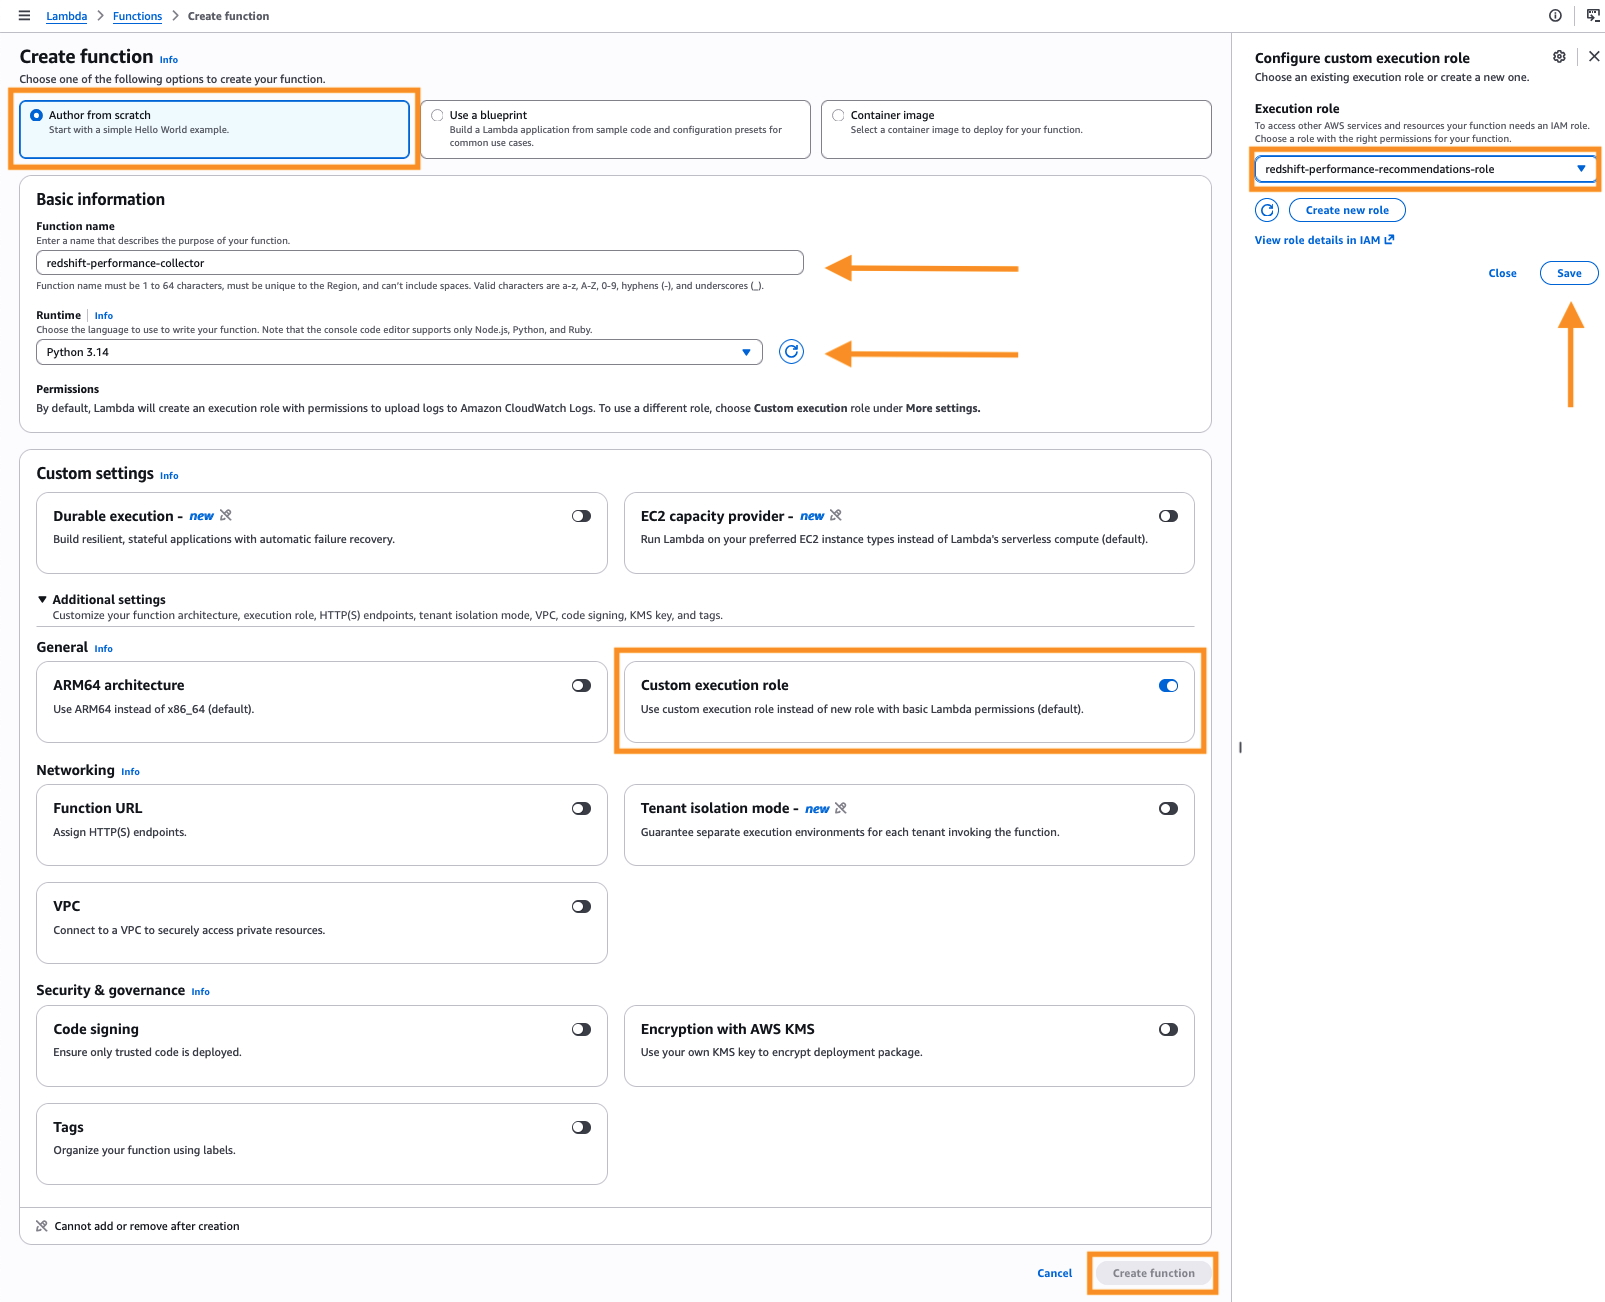
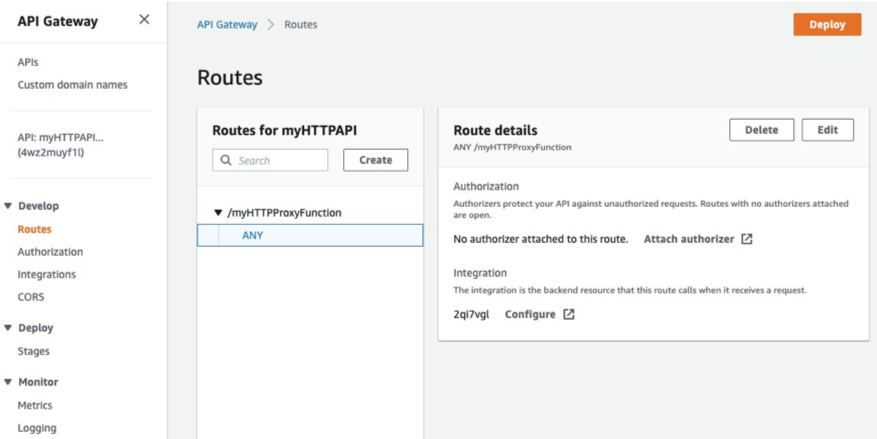
A browser request goes through Amazon’s API Gateway to a Python function on AWS Lambda, which runs when needed. That function reads an immutable SQLite snapshot. A new execution environment loads the pinned, compressed snapshot from private S3 storage into /tmp, checks its size and SHA-256, and opens it read-only. Later requests in that environment reuse it. CloudFront, Amazon’s content-delivery service, serves the website and hosted thumbnails.
The following abbreviated example shows the same request-and-render pattern used by this site. The production client also validates responses and image destinations, cancels superseded requests, handles errors and builds the artwork controls.
JavaScript · from a search request to visible results
async function showCollection() {
  const options = new URLSearchParams({
    imageCollection: 'true',
    page: '1',
    limit: '60'
  });
  const response = await fetch('/api/search?' + options);
  if (!response.ok) throw new Error('Search is unavailable');
  const result = await response.json();

  const cards = result.items.map(work => {
    const card = document.createElement('article');
    const title = document.createElement('h3');
    title.textContent = work.title;
    card.append(title);
    return card;
  });
  document.querySelector('#art-grid').replaceChildren(...cards);
}
The example renders titles as text. Explore adds imageCollection=true; Complete catalogue leaves it out. Search results include the matching total and timing fields. Database time, snapshot-loading time, server time and browser request time measure different parts of the trip.